Deploy Bare-Metal NVIDIA H200 Dedicated Servers

Accelerate Enterprise AI Inference with 141GB HBM3e Memory. Bypass the hypervisor tax and unpredictable spot pricing.
Deploy 100% single-tenant, bare-metal NVIDIA H200 dedicated servers starting at $4,105/month.
Engineered with single-socket AMD EPYC 9554P processors, 512GB DDR5 RAM, and up to 4.8 TB/s memory bandwidth,
our H200 infrastructure delivers unmatched token generation rates and zero-latency DDoS protection for massive Large Language Models (LLMs).
Secure your proprietary AI workloads natively within our globally compliant data center footprint today.

Explore Our Nvidia h200 GPU Dedicated Server Options

AMD EPYC 9554P
 NVIDIA H200 - 141GB HBM3e

 Basic Protection

43921  |  DC-252
FlagAmsterdam, Netherlands
  CORES3.10 GHz 64Cores 128Threads
  RAM512GB
  DISK8TB SSD
  Bandwidth1Gbps / 10TB
$4,926.00 /Mo$4,105.00 /Mo
Buy Now

AMD EPYC 9554P
 NVIDIA H200 -141GB HBM3e

 Basic Protection

43922  |  DC-252
FlagHague GPU, Netherlands
  CORES3.10 GHz 64Cores 128Threads
  RAM512GB
  DISK8TB SSD
  Bandwidth1Gbps / 10TB
$4,926.00 /Mo$4,105.00 /Mo
Buy Now
Global Availability

Deploy H200 in Premium
Global Locations.

Our H200 bare-metal infrastructure is actively expanding to provide ultra-low latency routing for your AI workloads globally.

Netherlands (Europe): Serving the Amsterdam and The Hague technological hubs via DC-252. Featuring premium backbone connectivity and absolute GDPR compliance.

Deploy H200

What is the NVIDIA H200 GPU?

The NVIDIA H200 is a data-center GPU built on the Hopper architecture, engineered to accelerate large language model (LLM) training and generative AI inference.

Featuring 141GB of HBM3e memory and 4.8 TB/s of memory bandwidth, the NVIDIA H200 GPU solves the critical memory bottlenecks found in previous generations.

This massive memory capacity allows foundation models—such as a 70B parameter model running in FP8 precision—to fit entirely on a single GPU with substantial headroom for KV caching, delivering significantly faster token generation rates for enterprise AI workloads.
Image of nvidia gpu dedicated servers
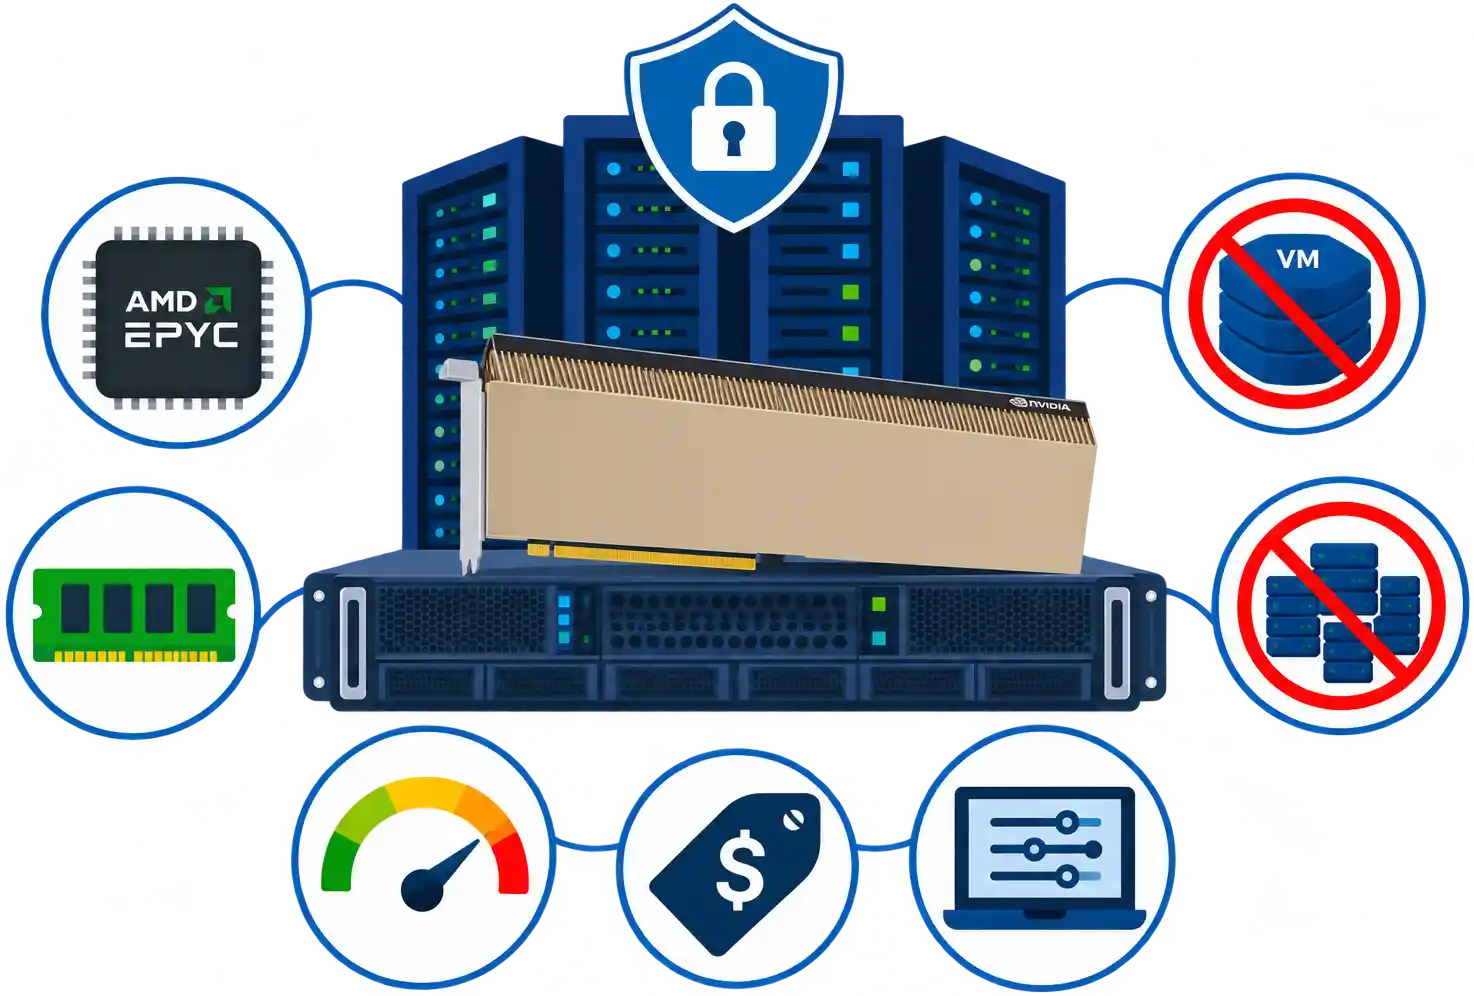
Dedicated NVIDIA H200 AI server with AMD EPYC CPU and enterprise data center security.

Why Rent an NVIDIA H200 Dedicated Server?

Renting an NVIDIA H200 dedicated server provides 100% bare-metal performance isolation without the hypervisor overhead or noisy-neighbor issues common in shared cloud environments.

Unlike unpredictable spot pricing or instances with hidden data transfer costs, our dedicated H200 servers offer a predictable flat-rate cost starting at $4,105/month.

Each node is powered by a single-socket AMD EPYC 9554P processor, 512GB of RAM, and true 1Gbps / 10TB bandwidth, giving you absolute control over your AI infrastructure while eliminating CapEx hardware depreciation risks.

How Does the H200 Compare to the H100?

The NVIDIA H200 builds upon the core Hopper GH100 die, delivering up to 3,958 TFLOPS of FP8 compute (with sparsity).

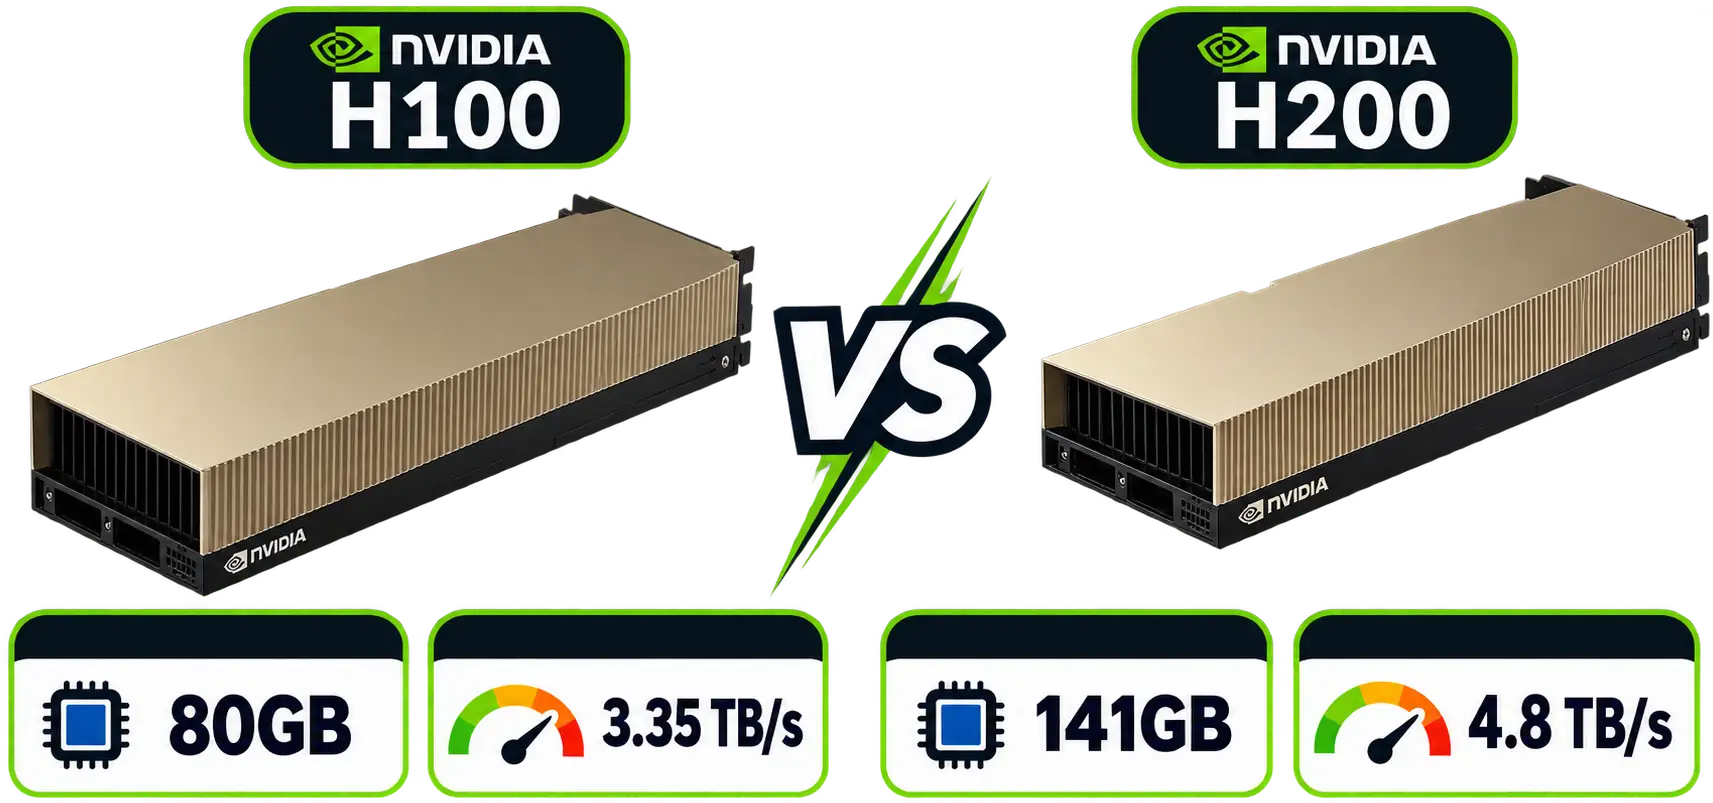
Compared to the H100 SXM, the H200 provides approximately 76% more memory capacity (141GB vs 80GB) and a 43% increase in memory bandwidth (4.8 TB/s vs 3.35 TB/s).

According to NVIDIA benchmarks, this bandwidth advantage allows the H200 to deliver up to 1.9x higher throughput performance on specific workloads like Llama 2 70B inference. This eliminates the need to shard mid-sized models across multiple GPUs, dramatically reducing latency during the memory-bound decode phase.
NVIDIA H100 vs H200 GPU comparison chart showing memory capacity and bandwidth specifications.

Ideal Use Cases for the NVIDIA H200

The enhanced memory bandwidth and capacity of the H200 make it a highly capable AI infrastructure for specific high-demand workloads.

Large Language Model (LLM) Inference

Optimized for serving large foundational models with stable response times and high token generation rates without multi-GPU overhead.

Retrieval-Augmented Generation (RAG)

Provides the massive KV cache headroom necessary to process extended context windows from proprietary vector databases.

Generative AI & Content Creation

Accelerates high-resolution text-to-image and multimodal processing pipelines that require extensive continuous VRAM.

Scientific Computing & HPC

Supports the high-bandwidth computational requirements for molecular dynamics, genome sequencing, and deep learning research.

Enterprise Security & Data Sovereignty

Fortified AI Infrastructure. Absolute Data Protection.

When deploying proprietary AI models, data sovereignty is critical. We provide a globally compliant, hardened foundation designed specifically to protect your most sensitive datasets and proprietary LLM models from sophisticated threats.

Bare-Metal Isolation

Total hardware exclusivity eliminates the vulnerabilities of shared cloud environments. Our single-tenant bare-metal architecture ensures your workloads, datasets, and model weights never share a hypervisor.

NVIDIA Confidential Computing

The NVIDIA H200 supports advanced hardware capabilities (TEE architecture) designed to create secure enclaves, protecting GPU workloads and sensitive data-in-use during processing (dependent on host configuration).

Advanced Threat Mitigation

All H200 deployments are fortified by robust LSN-NSFocus inline volumetric DDoS mitigation. We actively shield your raw compute cycles and inference pipelines from disruptive network-level volumetric attacks.

Global Compliance & Sovereignty

Host your proprietary AI models with absolute peace of mind. Our premium infrastructure guarantees strict data sovereignty and adheres to international compliance standards, ensuring your data remains within your legal jurisdiction.

Frequently Asked Questions

Is the NVIDIA H200 faster than the H100 for LLM Inference?

Yes, for memory-bound workloads. While both GPUs share similar raw compute power, the H200's 4.8 TB/s memory bandwidth significantly reduces decode-phase bottlenecks. NVIDIA benchmarks show the H200 delivering up to 1.9x higher throughput on specific workloads like Llama 2 70B inference compared to the H100.

Can I run a 70B parameter model on a single H200 GPU?

The NVIDIA H200 provides 141GB of HBM3e memory, which significantly reduces the need for multi-GPU partitioning. A 70B model running in FP8 precision (requiring ~70GB for weights) fits comfortably on a single H200, leaving ample VRAM for context length and KV caching. However, running the same model in unquantized FP16 (~140GB weights) would leave insufficient headroom for inference runtime overhead.

Does the $4,105/month ServerMO price include hidden egress fees?

No. Unlike hyperscale cloud providers that charge unpredictable per-GB egress fees, ServerMO’s NVIDIA H200 dedicated server includes a flat-rate 1Gbps / 10TB bandwidth allocation. (Please contact support for overage policies beyond 10TB).

How does ServerMO secure proprietary AI models on the H200?

We deploy 100% single-tenant bare-metal servers, ensuring your hardware resources are physically isolated and not shared via a hypervisor. Furthermore, the NVIDIA H200 hardware supports NVIDIA Confidential Computing, an architecture designed to protect data-in-use.
Power. Performance. Precision.

99.99% Uptime Guarantee
24/7 Expert Support
Blazing-Fast NVMe SSD

Christmas Mega Sale!

Unwrap the ultimate power! Get massive holiday discounts on all Dedicated Servers. Offer ends soon grab yours before the snow melts!

London UK (15% OFF)
Tokyo Japan (10% OFF)
00Days
00Hrs
00Min
00Sec
Explore Grand Offers